Engineered to end on-call burnout.
A unified observability and self-healing intelligence layer that puts resolution before alerts.
Cross-stack monitoring
Logs, metrics and traces from every service in one place. No more jumping between five dashboards during an incident.
Anomaly detection
Spots unusual behaviour in real time, before customers notice. Alerts arrive with context, not just a red graph.
Root-cause diagnosis
Explains why something broke, in plain language. Your on-call engineer starts from the answer, not from scratch.
Auto-remediation with human sign-off
Proposes the exact fix and applies it after approval. Every action is recorded for audit.
Multi-cloud
Works across AWS, GCP and Azure. One operating model for your whole estate.
Learns your runbooks
Trains on your SOPs and past incidents. Gets better at your environment over time.
Policy, RBAC and audit
Fine-grained permissions and a full audit log. Ready for compliance reviews.
Chat with your infrastructure
Ask questions in plain English and get answers from live data. Generate IaC and CI/CD pipelines from the same place.
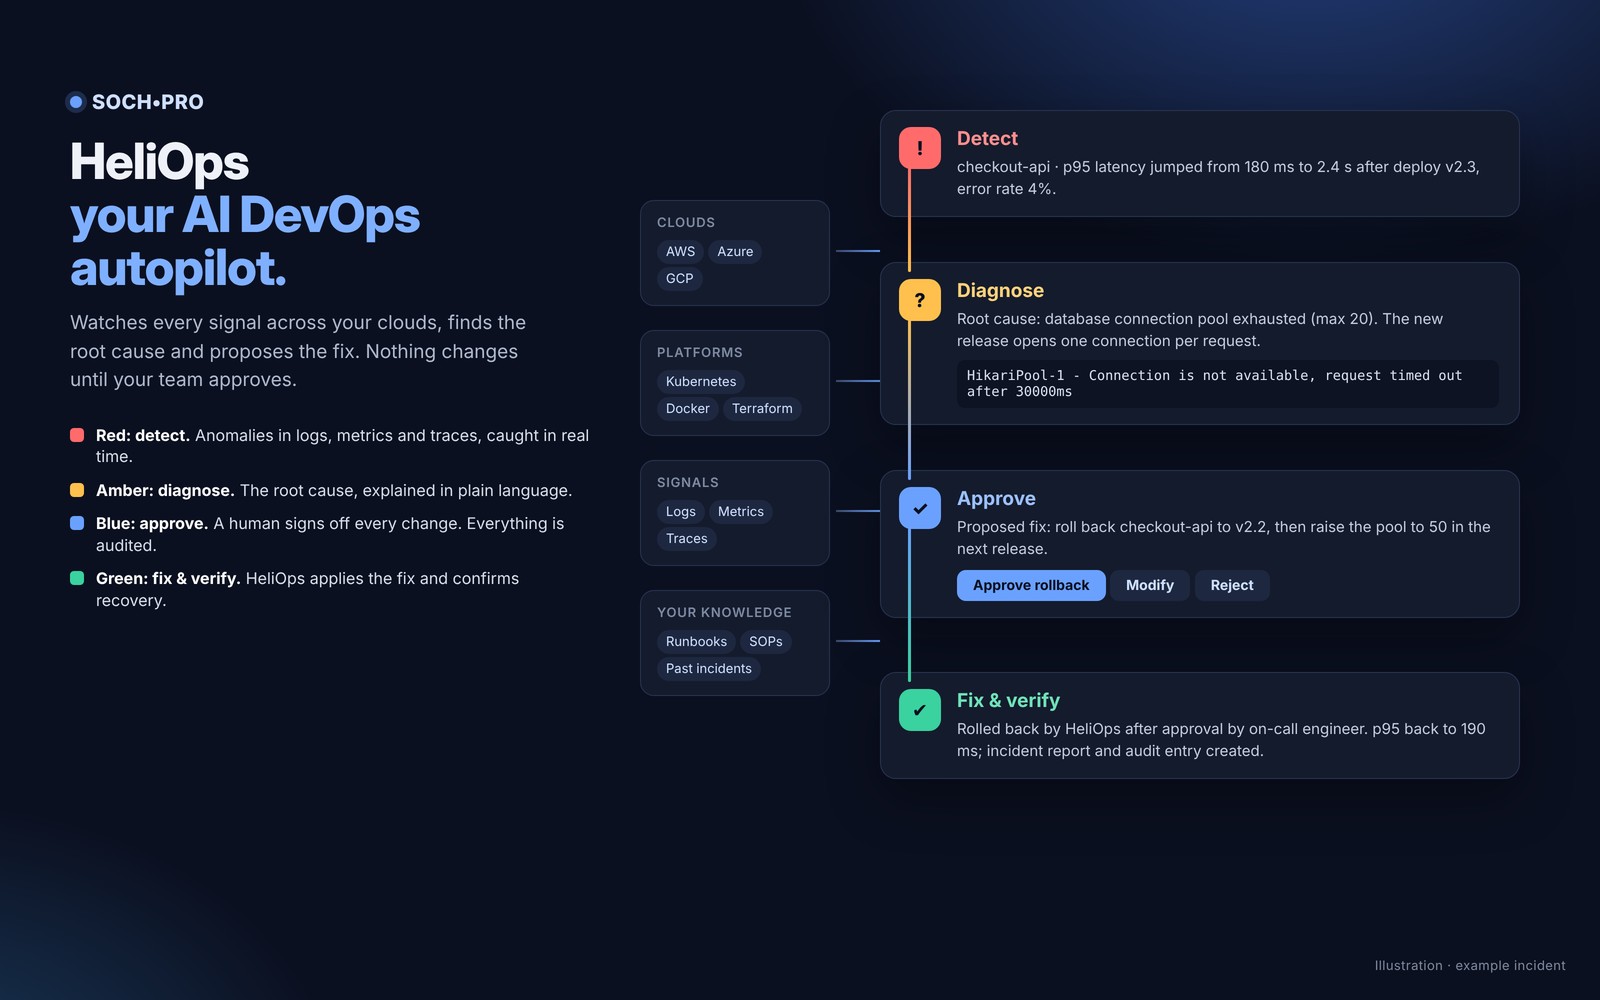
How HeliOps Works
Smarter Incident Resolution
Engineers start from root-cause diagnosis instead of log searching.
Human approval gates prevent accidental infrastructure drift.
Every suggestion, approval, and verification logged for compliance.